Extract Map Mode API
Map mode lists a website's URLs without extracting them, from the starting page's links and the website's
sitemaps. Each URL has a source of page or sitemap. Only the starting
host is included unless include_subdomains=true.
API Parameters
Mode
mode
Optional
Parameter defines the extraction mode. It can be set to:scrape (default) - Extract a single page.map - List the website's URLs from the page links and sitemaps.crawl - Follow links on the same website and extract every page visited.
Crawl mode consumes one search credit per successfully extracted page.
API Examples
Discover URLs for a host mode: map
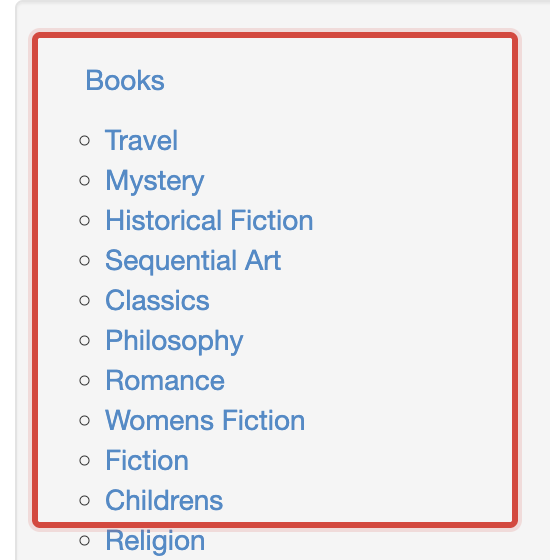
{
  ...
  "search_information": {
    "final_url": "https://books.toscrape.com/",
    "organic_results_state": "Map built"
  },
  "urls": [
    {
      "url": "https://books.toscrape.com/index.html",
      "title": "Books to Scrape",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books_1/index.html",
      "title": "Books",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks_1%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books/travel_2/index.html",
      "title": "Travel",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks%2Ftravel_2%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books/mystery_3/index.html",
      "title": "Mystery",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks%2Fmystery_3%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books/historical-fiction_4/index.html",
      "title": "Historical Fiction",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks%2Fhistorical-fiction_4%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books/sequential-art_5/index.html",
      "title": "Sequential Art",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks%2Fsequential-art_5%2Findex.html"
    },
    {
      "url": "https://books.toscrape.com/catalogue/category/books/classics_6/index.html",
      "title": "Classics",
      "source": "page",
      "serpapi_extract_link": "https://serpapi.com/search.json?device=desktop&engine=extract&url=https%3A%2F%2Fbooks.toscrape.com%2Fcatalogue%2Fcategory%2Fbooks%2Fclassics_6%2Findex.html"
    }
  ]
}
JSON Structure Overview
{
  ...
  "search_information": {
    "final_url": "String - URL of the starting page after redirects",
    "organic_results_state": "String - 'Map built', or 'Empty' if no URLs were found"
  },
  "urls": [
    {
      "url": "String - URL on the website",
      "title": "String - Link text of the URL (page URLs only)",
      "source": "String - Where the URL was found. Can be 'page' or 'sitemap'",
      "serpapi_extract_link": "String - Extract API link for extracting this URL next"
    },
    ...
  ]
}